
A simulation study answers a question about a system by building a model of it and running the model on a computer. Here the system is a shop that packs orders, and the question is whether it needs a third packer. A study goes through the same steps each time: get a model, check that it makes sense, look at what it produces, run it many times, compare the options, and base its inputs on real measurements.
desflow has a command for each step. The previous post said what changed in desflow 0.25.0. This post runs every command on one model and shows what each prints. Everything runs on your own machine, in one folder, without Docker.
Install
1pip install "desflow[fit]"
2desflow --version
10.25.0
The fit extra adds scipy and matplotlib, which only desflow fit needs. desflow on its own lists the commands, and --help after any command shows its options with examples.
Get the Model
desflow comes with example models. desflow examples list lists them, with any service, such as Kafka, that an example needs:
1$ desflow examples list
2local                prints events and telemetry, with no container (no service)
3kafka                takes updates from Kafka and publishes events and telemetry to Kafka (odctl up kafka-lite)
4parquet              a week generated unpaced, written to Parquet (no service)
5...
6experiment           two designs of the shop compared with paired replications, a check, observed waits and a report (no service)
7fitting              the packing time fitted from 40 measured times, then loaded into the shop (no service)
8related-records      orders and their line items, in two PostgreSQL tables (odctl up postgres)
desflow examples get downloads one into a folder named after it:
1$ desflow examples get experiment --api yaml
2wrote experiment/yaml/experiment.yaml
3wrote experiment/yaml/experiment_shop.yaml
4wrote experiment/observed_waits.csv
5
6Find the bottleneck, with no run: cd experiment/yaml && desflow explain experiment_shop.yaml
7Run the yaml version: cd experiment/yaml && desflow experiment experiment.yaml
experiment_shop.yaml is the model of the shop:
 1simulation:
 2  sim_id: Shop
 3  factor: 0              # run as fast as possible, not in real time
 4  random_seed: 42        # the same random draws on every run
 5
 6resources:
 7  packers: {current_cap: 2, max_cap: 4}       # 2 packers, at most 4
 8
 9services:
10  packing: {dist: gamma, shape: 4, scale: 1}  # 4 seconds on average, varying
11
12arrivals:
13  orders: {dist: exponential, rate: 0.4, spawn: pack}   # an order every 2.5 seconds on average
14
15tasks:
16  pack:
17    service: packing
18    resource: packers
19    payload: {event_type: order_packed}
Orders arrive at random moments, every 2.5 seconds on average. Each one waits for a free packer, and packing takes 4 seconds on average, sometimes more and sometimes less. experiment.yaml is the study that compares two packers with three, and observed_waits.csv holds the wait measured in the real shop. The commands below run from experiment/yaml:
1cd experiment/yaml
Check It Makes Sense
Before running anything, it helps to know whether the packers can keep up. Queueing theory, the mathematics of waiting lines, describes a line such as the shop’s with a few numbers, each written as a letter:
- λ (lambda), the arrival rate: how many orders arrive a second. An order every 2.5 seconds is 0.4 a second.
- μ (mu), the service rate: how many orders one packer finishes a second. Packing takes 4 seconds, so one packer finishes 0.25 a second.
- c, the capacity: the number of packers, 2.
- ρ (rho), the utilisation: the share of time the packers are busy. Two packers finish c × μ = 0.5 orders a second while 0.4 arrive, so ρ = λ ÷ (c × μ) = 0.4 ÷ 0.5 = 0.8. They are busy 80% of the time.
When ρ is 1 or more, orders arrive faster than they are packed, and the queue grows for as long as the shop stays open.
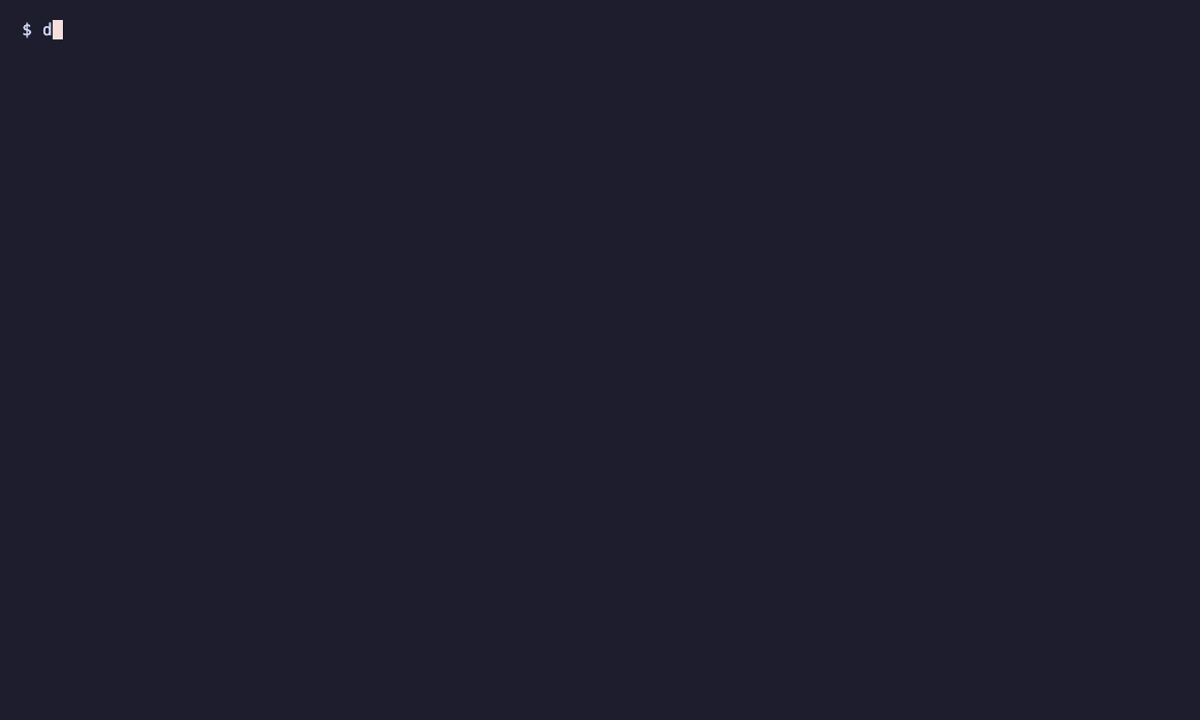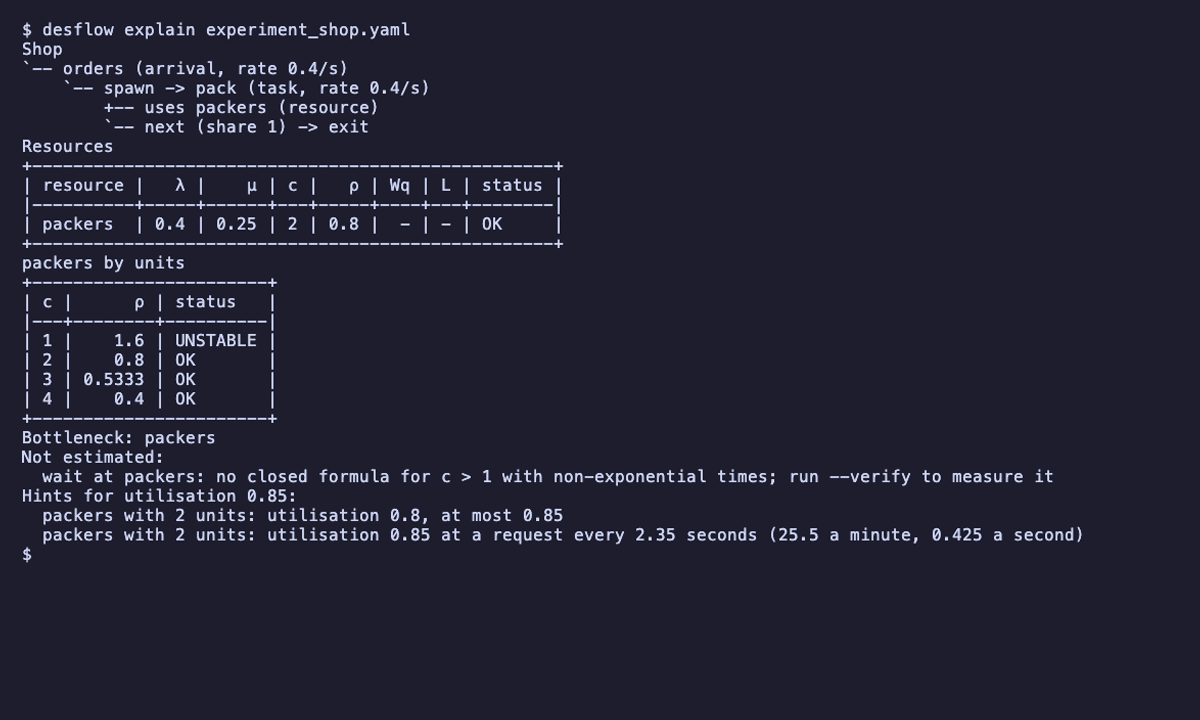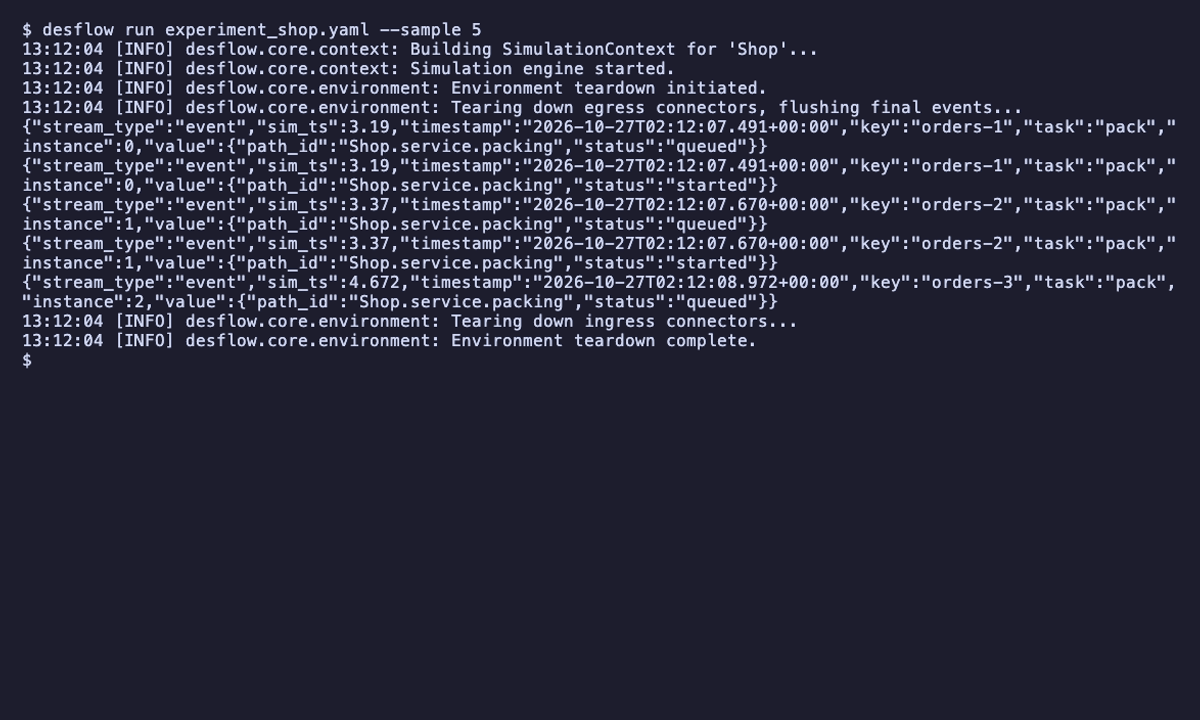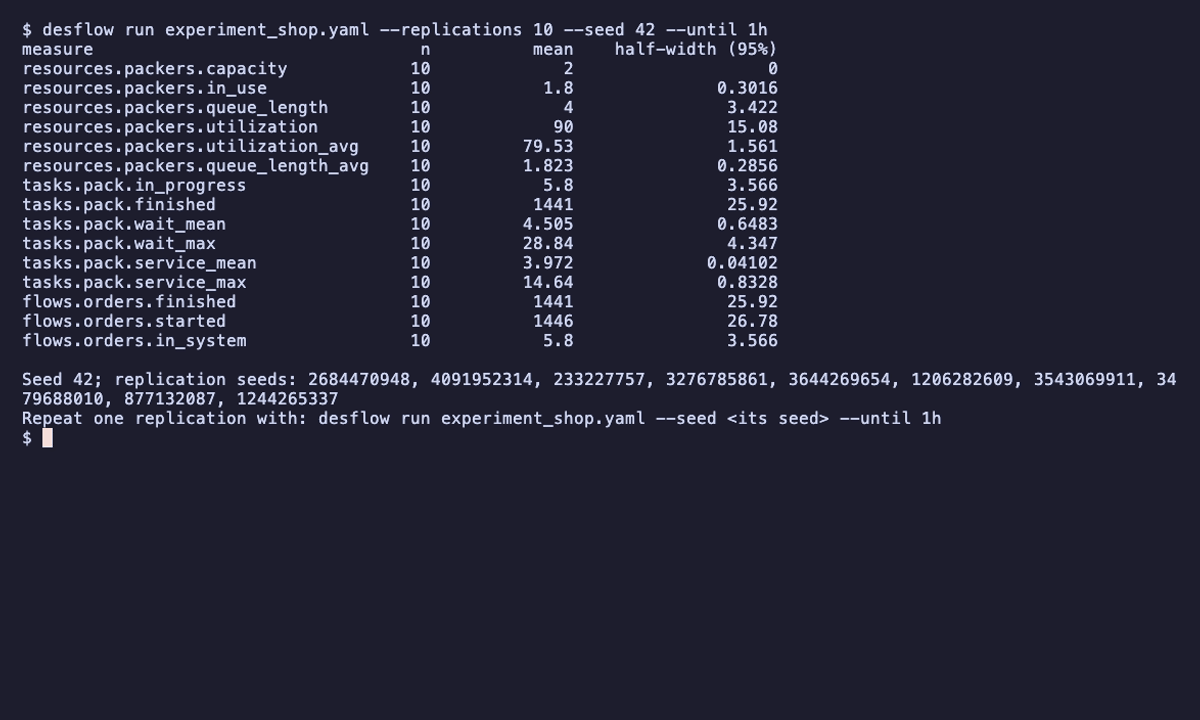
desflow explain works these numbers out from the model, for every resource, and prints them:
 1$ desflow explain experiment_shop.yaml
 2Shop
 3`-- orders (arrival, rate 0.4/s)
 4    `-- spawn -> pack (task, rate 0.4/s)
 5        +-- uses packers (resource)
 6        `-- next (share 1) -> exit
 7Resources
 8+---------------------------------------------------+
 9| resource |   λ |    μ | c |   ρ | Wq | L | status |
10|----------+-----+------+---+-----+----+---+--------|
11| packers  | 0.4 | 0.25 | 2 | 0.8 |  - | - | OK     |
12+---------------------------------------------------+
13packers by units
14+-----------------------+
15| c |      ρ | status   |
16|---+--------+----------|
17| 1 |    1.6 | UNSTABLE |
18| 2 |    0.8 | OK       |
19| 3 | 0.5333 | OK       |
20| 4 |    0.4 | OK       |
21+-----------------------+
22Bottleneck: packers
23Not estimated:
24  wait at packers: no closed formula for c > 1 with non-exponential times; run --verify to measure it
25Hints for utilisation 0.85:
26  packers with 2 units: utilisation 0.8, at most 0.85
27  packers with 2 units: utilisation 0.85 at a request every 2.35 seconds (25.5 a minute, 0.425 a second)
The output reads from the top:
- Graph: each order starts a
packtask, which uses a packer and then leaves.rate 0.4/sis λ. - Resources: λ, μ, c and ρ for the packers, as worked out above. Wq is the average time an order waits in the queue, and L is the average number of orders in the shop, waiting or being packed.
statusisOKwhile ρ is below 0.85,CONGESTEDfrom 0.85, where the queue gets long quickly, andUNSTABLEfrom 1. - packers by units: ρ for one to four packers, which shows how many packers the shop needs. One packer gives ρ = 0.4 ÷ 0.25 = 1.6, so it is
UNSTABLE. - Bottleneck: the resource with the highest ρ.
- Not estimated: Wq and L are blank. A formula gives them only for simpler shops, such as one with a single packer, so
explainsays so rather than guess. - Hints: 0.85 is where
CONGESTEDstarts. The first line says two packers are below it. The second gives the arrival rate at which they reach it, only a little faster than the order every 2.5 seconds the shop has now.
--verify runs the model to measure what no formula gave, and to check the arithmetic. Here it runs one hour of the shop ten times:
 1$ desflow explain experiment_shop.yaml --verify --replications 10 --until 1h
 2...
 3Verify: 10 runs to 3600 s, seed 42
 4+------------------------------------------------------------------------+
 5| node    | measure      | analysis | measured |        ± | result       |
 6|---------+--------------+----------+----------+----------+--------------|
 7| packers | utilization  |      0.8 |   0.7953 |  0.01561 | agrees       |
 8| packers | queue_length |        - |    1.823 |   0.2856 | not compared |
 9| pack    | wait         |        - |    4.505 |   0.6483 | not compared |
10| orders  | throughput   |      0.4 |   0.4002 | 0.007201 | agrees       |
11+------------------------------------------------------------------------+
The ... stands for the same output as before. Each row of the table is one measure of one part of the model:
- node: the part measured: the
packers, thepacktask or theordersarrival. - measure: what was measured.
throughputis how many orders leave the shop a second. - analysis: the value the arithmetic gives, or
-where no formula applies. - measured: the average over the ten runs.
- ±: give or take: the true average very likely lies within this distance of the measured one (a 95% confidence interval).
- result:
agreeswhen the analysis lies within that range,differswhen it does not, andnot comparedwhen there is no analysis to compare. The packers are as busy as the arithmetic says, and orders leave as fast as they arrive, so the model does what its settings describe. The runs also measure the wait, which the arithmetic could not give.
Look at What It Produces
A model produces events: one record each time something happens to an order. desflow run --sample prints the first few, without sending anything to the model’s destinations, such as Kafka or a database:
1$ desflow run experiment_shop.yaml --sample 5
2{"stream_type":"event","sim_ts":3.19,"timestamp":"2026-10-27T01:47:34.769+00:00","key":"orders-1","task":"pack","instance":0,"value":{"path_id":"Shop.service.packing","status":"queued"}}
3{"stream_type":"event","sim_ts":3.19,"timestamp":"2026-10-27T01:47:34.769+00:00","key":"orders-1","task":"pack","instance":0,"value":{"path_id":"Shop.service.packing","status":"started"}}
4{"stream_type":"event","sim_ts":3.37,"timestamp":"2026-10-27T01:47:34.949+00:00","key":"orders-2","task":"pack","instance":1,"value":{"path_id":"Shop.service.packing","status":"queued"}}
5{"stream_type":"event","sim_ts":3.37,"timestamp":"2026-10-27T01:47:34.949+00:00","key":"orders-2","task":"pack","instance":1,"value":{"path_id":"Shop.service.packing","status":"started"}}
6{"stream_type":"event","sim_ts":4.672,"timestamp":"2026-10-27T01:47:36.250+00:00","key":"orders-3","task":"pack","instance":2,"value":{"path_id":"Shop.service.packing","status":"queued"}}
Each order is queued when it joins the line and started when a packer takes it. The first two orders find a packer free and start at once. sim_ts is the time in the simulation, in seconds from the start.
--stdout prints every record of a full run instead of sending it on, so it can go to a file. This line runs the shop for 20 seconds, then lets the orders still inside finish:
1desflow run experiment_shop.yaml --seed 42 --until 20 --drain --stdout > records.jsonl
Run It Many Times
Arrival and packing times are random, so each run gives a slightly different answer. One run is like one day in the shop: a quiet day or a busy one by chance. --replications runs the model several times, each with different random draws, and reports the average of each measure with a range around it:
 1$ desflow run experiment_shop.yaml --replications 10 --seed 42 --until 1h
 2measure                                n          mean    half-width (95%)
 3resources.packers.capacity            10             2                   0
 4resources.packers.in_use              10           1.8              0.3016
 5resources.packers.queue_length        10             4               3.422
 6resources.packers.utilization         10            90               15.08
 7resources.packers.utilization_avg     10         79.53               1.561
 8resources.packers.queue_length_avg    10         1.823              0.2856
 9tasks.pack.in_progress                10           5.8               3.566
10tasks.pack.finished                   10          1441               25.92
11tasks.pack.wait_mean                  10         4.505              0.6483
12tasks.pack.wait_max                   10         28.84               4.347
13tasks.pack.service_mean               10         3.972             0.04102
14tasks.pack.service_max                10         14.64              0.8328
15flows.orders.finished                 10          1441               25.92
16flows.orders.started                  10          1446               26.78
17flows.orders.in_system                10           5.8               3.566
18
19Seed 42; replication seeds: 2684470948, 4091952314, 233227757, 3276785861, 3644269654, 1206282609, 3543069911, 3479688010, 877132087, 1244265337
20Repeat one replication with: desflow run experiment_shop.yaml --seed <its seed> --until 1h
Read tasks.pack.wait_mean as: orders wait 4.5 seconds on average, give or take 0.65. The true average is very likely within that range (a 95% confidence interval). More runs make the range narrower.
A measure ending in _avg is averaged over the whole hour. One without it, such as utilization, is a single reading at the moment the run ends. That is why its range is so much wider. The last line gives the command that repeats any one of the ten runs exactly.
Compare Two Options
Would a third packer keep the average wait under 2 seconds? desflow experiment answers that from a file. It runs one hour of the shop 20 times with two packers and 20 times with three:
 1experiment: packers
 2question: Does a third packer keep the mean wait under 2 seconds?
 3model: experiment_shop.yaml
 4until: 1 h
 5warmup: 3 min              # leave out the first 3 minutes, when the shop is still empty
 6replications: 20
 7seed: 42
 8pairing: common            # both versions see the same orders
 9measures: [tasks.pack.wait_mean, resources.packers.utilization_avg]
10variants:
11  two: {}
12  three: {Shop.resources.packers.current_cap: 3}
13compare:
14  - {baseline: two, variant: three}
15checks:
16  - {measure: tasks.pack.wait_mean, variant: three, max: 2}
17observed:
18  file: ../observed_waits.csv   # the mean wait measured in the real shop
19  variant: two                  # the real shop has two packers
20output: results/packers
1$ desflow experiment experiment.yaml --output results/packers
2Wrote the artifacts and report.md to results/packers
3passed: three: tasks.pack.wait_mean max 2, checked 0.5919
Both versions see the same orders at the same times, so a difference between them comes from the third packer, not from luck. The check passes: with three packers, even the top of the range of the average wait is under 2 seconds. The report, report.md, puts the two side by side:
| Packers | Average wait (s) | Range | Packers busy (%) |
|---|---|---|---|
| two | 4.872 | 4.323 to 5.422 | 80.56 |
| three | 0.5389 | 0.4859 to 0.5919 | 53.74 |
The experiment also compares two packers with the real shop. The wait measured there falls inside the range the model gives for two packers, which is evidence that the model describes the shop well. The command fails when a check fails, so it can run in a CI pipeline. desflow report results/packers builds the report again from the saved results, without running anything.
Base the Inputs on Measurements
The packing time in a model should come from measured times, not a guess. Measured times vary, and the model needs the shape of that variation: a distribution. The fitting example holds 40 packing times timed at a bench, and desflow fit tries each kind of distribution on them:
 1$ desflow examples get fitting --api yaml
 2$ desflow fit fitting/packing_times.csv --column packing_seconds --lower 0
 340 rows: 40 used, 0 missing, 0 invalid
 4family            status              AIC  KS stat KS p (approx.)  parameters or reason
 5exponential       rejected                                         its std is 1.5, the data's is 0.4832: more than 25% apart
 6normal            fitted            59.33    0.157         0.2504  mean=1.5, std=0.483218 (can draw below the lower bound 0)
 7lognormal         fitted            57.33  0.09406         0.8385  mean=1.50251, std=0.511854
 8truncated_normal  fitted            59.25   0.1558         0.2579  mean=1.49836, std=0.48579, low=0
 9constant          skipped                                          the values are not all equal
10uniform           fitted            59.45    0.225        0.02923  low=0.7, high=2.7
11triangular *      fitted            56.68   0.1258          0.511  low=0.546332, mode=1.2, high=2.83766
12gamma             fitted            56.79   0.1157         0.6165  shape=9.55777, scale=0.15694
13weibull           fitted            58.99   0.1502         0.2972  shape=3.33522, scale=1.67203
14empirical         fitted                                           values: 40 numbers
15* best: triangular
Each row is one kind of distribution. AIC scores how well it fits, and lower is better. The KS p column tests whether the fit is believable at all: a value near 0, as for uniform, means it is not. The triangular fits best, just ahead of the gamma. --lower 0 says a time cannot be negative, which is why the normal is flagged. --out writes the best fit as a setting the model can load.
desflow dist converts in the other direction. Given an average and a spread, it gives the settings a distribution needs:
1$ desflow dist gamma --mean 1.5 --std 0.4832
2parameters: shape 9.63671, scale 0.155655
3mean 1.5, std 0.4832
4variability: low (std / mean 0.322)
5with no random generator, every draw is 1.5
6YAML: {dist: gamma, shape: 9.63671, scale: 0.155655}
7Python: dist="gamma", shape=9.63671, scale=0.155655
The last two lines are ready to paste into a model. desflow dist on its own lists every kind of distribution.
Set Up an Editor
desflow schema prints a description of every setting a model can have, as a JSON Schema:
1desflow schema > blueprint.schema.json
With the Red Hat YAML extension in VS Code, this line at the top of a model makes the editor suggest settings and mark a misspelt one as you type:
1# yaml-language-server: $schema=./blueprint.schema.json
Set Up Your Editor shows other ways to point the editor at it.
Every Command in One Place
| Command | What it does |
|---|---|
desflow examples | lists the example models and downloads one |
desflow explain | checks that a model makes sense, without running it, and with --verify by running it |
desflow run | runs a model, prints its first events, or runs it many times |
desflow experiment | compares versions of a model and writes a report |
desflow report | builds an experiment’s report again from its saved results |
desflow fit | finds the distribution that matches measured times |
desflow dist | lists the distributions and converts their settings |
desflow schema | prints the description of every setting, for an editor |
Each command calls the same library function a Python script would, so both give the same result. Command Line has every option on the same shop, and CLI gives the help of every command.
Related Posts
- From dynamic-des to desflow: What Changed in Five Releases - what each command was added for
- Defining Data-Streaming Simulations in YAML, Without Writing Python - the YAML format the shop is written in
Try It Out
1pip install "desflow[fit]"
2desflow examples get experiment --api yaml
3cd experiment/yaml && desflow explain experiment_shop.yaml
- GitHub: jaehyeon-kim/desflow
- PyPI: pypi.org/project/desflow
- Documentation: jaehyeon.me/desflow


Comments