Open Data Stack (odctl)
Run an open data stack on your machine, with its services already connected, from one command.
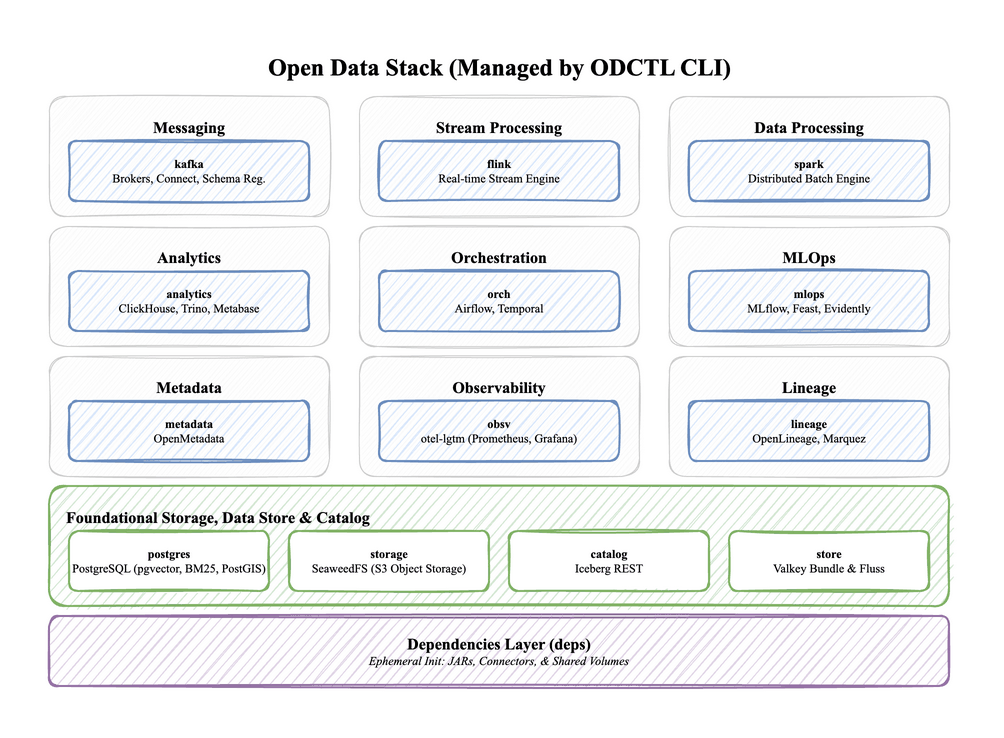
odctl is a command-line tool that runs an open data stack on your machine with Docker Compose. You name the profiles you want, such as kafka-lite or airflow, and odctl starts them together with the services they depend on.
A Compose file of your own is enough for one small project. Why odctl explains what odctl adds when several projects need different parts of the stack.
Commands
Each command has its own section in the CLI reference, with its options and examples. The Example column links to a page that runs the command and shows its output, and Getting Started runs them in order on one profile.
| Command | Use it to | Example |
|---|---|---|
odctl list |
See every profile and what it runs | Getting Started |
odctl explain |
See a profile's services, images, ports and the profiles it depends on | Getting Started |
odctl ps |
See the running containers, their health and their ports | Getting Started |
odctl info |
Check the installed odctl version and whether Docker is reachable | Getting Started |
odctl init |
Copy the compose files and settings into .odctl, so you can edit them |
Getting Started |
odctl pull |
Download a profile's images before you start it | How It Works |
odctl up |
Start profiles and the profiles they depend on | Getting Started |
odctl down |
Stop profiles and remove their containers | Getting Started |
odctl logs |
Read the logs of a profile's containers | Getting Started |
odctl restart |
Restart a profile's containers and keep them | Getting Started |
odctl recreate |
Replace a profile's containers, to apply an edit to a compose file or .env |
How It Works |
What It Runs
| Area | Technologies |
|---|---|
| Messaging | Kafka (KRaft), Karapace schema registry, Kafka Connect, Kafka UI (kafbat) |
| Stream and Batch Processing | Apache Flink, Apache Spark |
| Analytics | ClickHouse, Trino, Metabase |
| Orchestration | Apache Airflow, Temporal |
| MLOps | MLflow, Feast, Evidently |
| Metadata and Lineage | OpenMetadata, Marquez |
| Observability | grafana/otel-lgtm (OpenTelemetry Collector, Prometheus, Tempo, Loki, Grafana) |
| Storage and Catalog | PostgreSQL 18 with pgvector, pg_textsearch and PostGIS, SeaweedFS (S3), Iceberg REST catalog, Valkey Bundle, Apache Fluss |
Kafka Connect comes with a set of connectors, such as the Iceberg sink and the Debezium PostgreSQL source. Kafka Connect lists them all.
Where to Go Next
- Why odctl says why odctl exists and what it is for.
- Getting Started installs odctl and starts a first profile.
- Profiles lists every profile with its ports, images and memory limits.
- Guides show how to use each service, starting with Kafka.
Projects That Use odctl
- benchtop: data engineering and machine learning projects, each run from a cold clone on odctl.
- desflow (docs): a SimPy library for simulations that stream to Kafka, PostgreSQL, Redis and Iceberg.
- agentic-analytics-system: conversational analytics over an Iceberg lakehouse.
Blog posts about odctl and these projects are tagged odctl on jaehyeon.me.